RicePredict
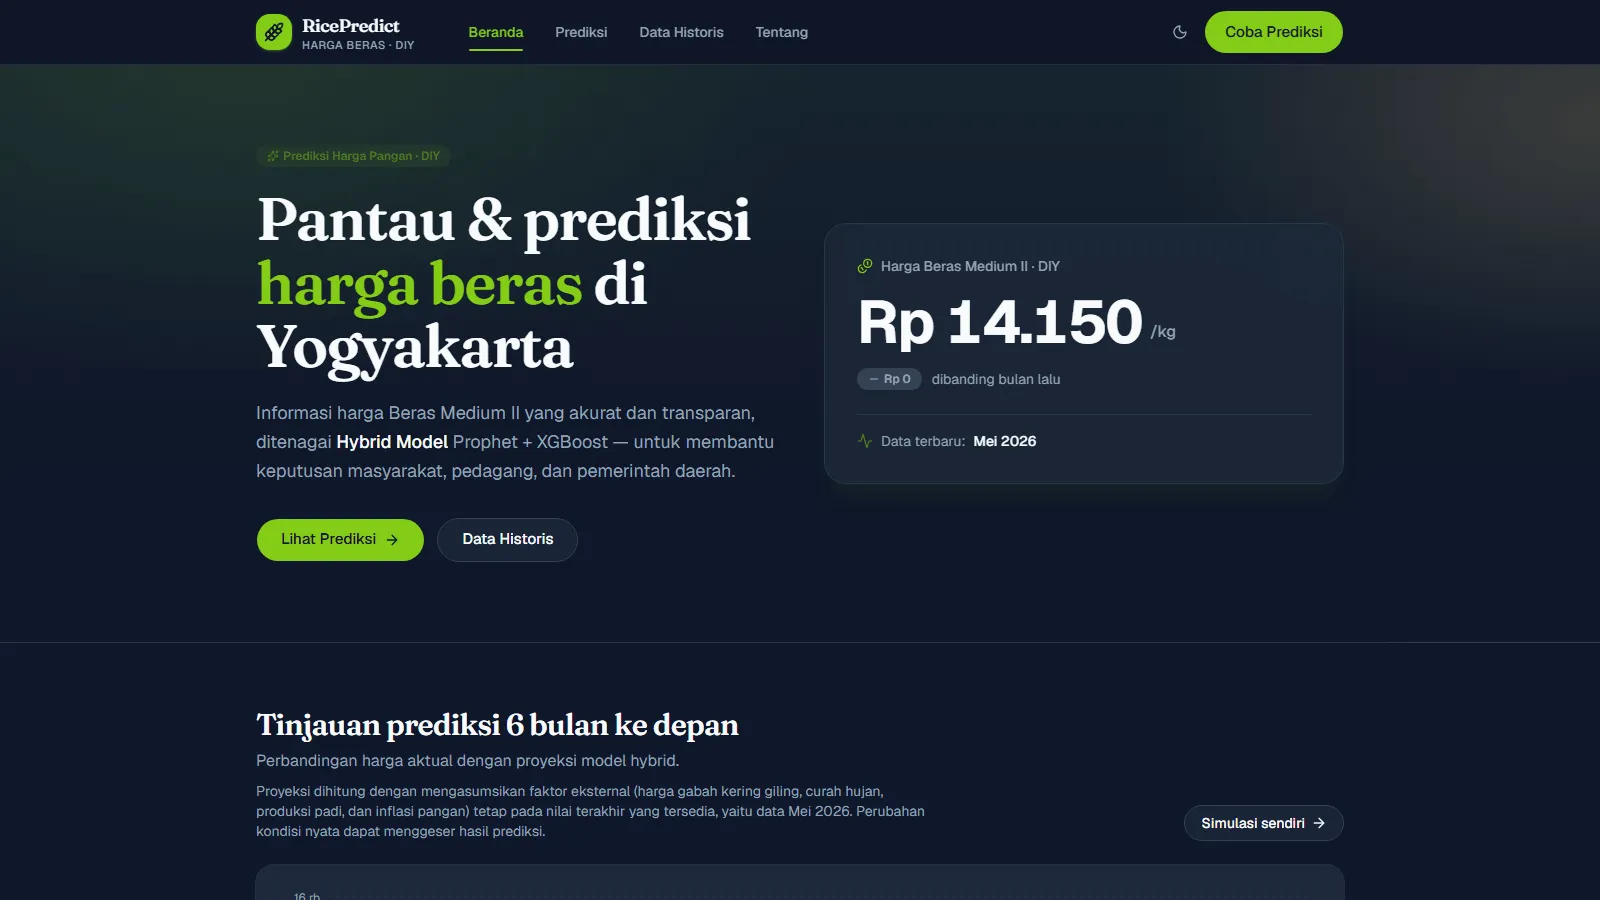
A public forecasting tool for medium-grade rice prices in Yogyakarta, built to close the information gap between traders who track the market daily and households who do not.
- Role
- Full-stack Developer & ML Engineer
- Timeline
- 4 months (May — September 2026)
- Team
- Solo. Undergraduate thesis project.
- Year
- 2026
Stack
- Next.js
- TypeScript
- FastAPI
- Prophet
- XGBoost
- PostgreSQL
- Recharts
Outcomes
- MAPE of 2.93% when external conditions are known, and 9.91% forecasting blind from the latest available month
- Six-month forecasts published openly, sourced from four public datasets
- Both error figures shown on the site, so users can judge how much to trust a number
Context
Rice is the staple food in Indonesia, and its price moves constantly. In Yogyakarta that movement is tracked closely by traders and government agencies, but the raw data sits across several government portals in formats a normal person will never open.
RicePredict is my undergraduate thesis: a public web application that forecasts the price of Beras Medium II in the Special Region of Yogyakarta up to six months ahead. I built the machine learning pipeline and the web application end to end, over four months.
The problem
The gap is not a lack of data. It is information asymmetry.
A trader who watches the market daily knows when prices are about to climb. A household buying rice weekly finds out at the till. The underlying numbers, grain prices, rainfall, rice production, food inflation, are all public, but they are scattered across PIHPS Nasional, the National Food Agency, BPS and weather services, in separate formats and on separate schedules.
I wanted to turn that into one page that answers a plain question: what is rice likely to cost in a few months, and how much should I trust that answer?
My role
Solo, across the whole stack:
- Data: collecting and aligning four public sources onto a common monthly index
- Modelling: the hybrid forecasting model and its evaluation
- Backend: a FastAPI service exposing the model
- Frontend: the Next.js application, charts and the way results are explained
- Deployment: a monorepo with a
Makefilethat starts both servers with one command
Technical decisions
A hybrid model instead of one model
I started with Facebook Prophet alone. It handles the parts of this problem that classical regression struggles with: long-term trend, yearly seasonality tied to harvest cycles, and external regressors for grain price, rainfall, production and food inflation.
Prophet got the shape of the curve right, but it left structure in its errors. The residuals were not noise. They still carried information from recent price history that an additive model does not capture.
So I added a second stage. XGBoost trains on Prophet’s residuals, using lag features from price history to correct what the first model systematically misses. Prophet explains the trend and the seasonality; XGBoost cleans up what is left.
I chose this over a single deep learning model deliberately. With monthly data over a limited history, an LSTM would have had far too many parameters for the number of observations. The hybrid keeps each component interpretable: I can still show a user which external factors are moving the forecast.
Publishing two accuracy numbers instead of one
This is the decision I am most confident was right, and it is a product decision as much as a technical one.
Evaluated in scenario mode, where the external factors for the target month are known or assumed, the model reaches MAPE 2.93% (MAE Rp 426, RMSE Rp 637). That is the honest measure of the model itself.
But that is not how someone actually uses the site. A visitor forecasting three months out does not know next month’s rainfall. Running with only the latest available data, real-world MAPE is about 9.91%.
It would have been easy to publish 2.93% and stop. Instead the site shows both, explains the difference, and states plainly that projections assume external factors hold at their last known values. A forecasting tool that hides its error bars is worse than no tool, because it invites confident bad decisions.
Indonesian interface
The audience is people in Yogyakarta buying and selling rice. The entire interface is in Indonesian, including the explanation of what MAPE means, so the accuracy figures are not just decoration for people without a statistics background.
The hardest problem
Aligning four data sources that disagree about time.
Price data, grain prices, production figures, rainfall and inflation all publish on different schedules, with different lags and different levels of regional granularity. Some are monthly, some are effectively continuous, some arrive weeks late.
The first pipeline I built quietly used data that would not have existed at prediction time. The model looked excellent, because it was partly reading the answer. That is target leakage, and it is dangerous precisely because it makes your metrics better.
Fixing it meant rebuilding the feature pipeline so every input is lagged to what was genuinely available at the moment of prediction. Accuracy dropped. That drop was the point: the earlier number was fiction.
Outcome
- A live, public site with six-month forecasts for medium-grade rice in DIY
- MAPE 2.93% in scenario mode, 9.91% forecasting blind
- Automatic market highlights that translate raw movements into plain language, for example flagging a 113mm rainfall drop as a risk to harvest volume
- Historical data and methodology published, so the forecast can be argued with
What I would do differently
Automate ingestion. Data updates are still manual. A scheduled job pulling from each source, with validation, would keep the site current without me.
Show uncertainty visually. The site reports aggregate error metrics, but the forecast chart draws a single line. Prophet produces confidence intervals natively and I should render them as a band. A line implies a precision the model does not have, and given how much effort I spent being honest about accuracy in text, the chart should say the same thing.
Retrain on a schedule. The model is trained once. Prices drift, and a forecasting system that never retrains slowly becomes a historical artifact.